Testable code: making the (testing) world better
Testable code: making the (testing) world better
What does it mean to have testable code? In general, it means, that the code is easy to test and it’s easy to set up a testing environment. Sometimes it’s tough to make code testable, especially in a large, legacy codebase, but I’d like to tell you some approaches and tips, that could help you make your code more maintainable, understandable, and reliable.
Currently, I’m working on splitting a big legacy monolith into small and handy microservices. This kind of activity often goes together with refactoring and fixing old problems. If we are starting with a fresh new project, then why not do things right (again?) at the beginning?
My story is about some notorious programming problems I was facing and how I solved these problems.
Global variables
Global variables are variables with global scope, which means that they are generally accessible from any place of the program. I’ll be sloppy and won’t talk about some exceptions, because they don’t change the overall picture.
var = 0


def increment():
    global var
var += 1or:
class Holder:


    def __init__(self):
        self.value = 0


    def increment(self):
        self.value += 1


    def decrement(self):
        self.value -= 1


shared_holder = Holder()


def increment():
shared_holder.increment()or even:
# database.py
engine, db = create_db('<URI>')


# another.py
from .database import db # `create_db` is called during the import Is this familiar? Global variables are not bad but often used in the wrong context. Context is what matters.
We have to use the right tool for the right job
Let’s look at what happens when global variables are misused.
It’s hard to test
Having global variables makes it harder to set up a clean environment for a test. It means that the global state is shared across test runs. If you change a global state, then you’ll have to reset it for the next test, and so on.
def test_increment():
    shared_holder.increment()
    assert shared_holder.value == 1


def test_decrement():
    shared_holder.decrement()
assert shared_holder.value == -1The test failed because the shared_holder object is the same in both tests and it was modified during the first test. Which test will fail in this suite depends on the execution order, which is another bad thing.
Makes thread-safety implementation more complicated
Having global variables accessible by multiple threads often implies usage of synchronisation mechanisms, which makes the code more complicated and also affects performance.
The naive, not thread-safe version:
import threading
import time


def increment():
    for i in range(500000):
        shared_holder.increment()


if __name__ == '__main__':
    start = time.time()
    threads = [threading.Thread(target=increment) for i in range(2)]


    for thread in threads:
        thread.start()
    for thread in threads:
        thread.join()


    print(shared_holder.value)
print(time.time() - start)$ python not_thread_safe.py
889706
0.2428889274597168Thread-safe version:
class Holder:


    def __init__(self):
        self.value = 0
        self._lock = threading.Lock()


    def increment(self):
        with self._lock:
self.value += 1$ python thread_safe.py
1000000
0.49862122535705566If someone can change it — you can’t rely on it.
Therefore using a global state usually makes the program less predictable and more complicated. Also, it makes debugging harder since it will be harder to detect who changed a global variable. And, consequently, it makes people less interested in writing tests or refactoring.
But, you can’t entirely avoid a global state, because something’s always global. For example, the runtime environment is global. Your os, sysare both in this category. It’s handy to use global variables in small and simple programs with a few modules if it doesn’t introduce the complexity mentioned above, or at the very least, this behaviour is isolated and manageable.
How to (not) fix it
In some cases, to make things work, you could monkey patch the module with a newly created object. In large projects, it could lead to monkey patching a significant amount of different modules.
# holder.py
# Holder class & global variable from above


# decrementer.py
from .holder import shared_holder


def decrement():
    shared_holder.decrement()


# test_holder.py
import pytest


from . import decrementer, holder


@pytest.fixture
def new_holder():
    return holder.Holder()


@pytest.fixture(autouse=True)
def patched(monkeypatch, new_holder):
    monkeypatch.setattr(decrementer, 'shared_holder', new_holder)


def test_holder():
    holder.shared_holder.increment()
    assert holder.shared_holder.value == 1


def test_decrementer():
    decrementer.decrement()
assert decrementer.shared_holder.value == -1In the example above, the monkeypatch fixture from py.test is used. It allows you to modify objects and rollback these changes automatically.
The patched fixture monkey patches the loaded module with freshly created Holder instance. If you remove this fixture, then test_decrementer will fail, because it will use a global variable that changed in test_holder.
In this situation, we have only two tests, and we need to add special machinery to make things work. If there would be more modules where the global state could change, the complexity would increase dramatically. As a project grows with speed, it’s almost impossible to know where and how the global state was changed. Fixing these things will be even harder, especially if you have dynamic imports and global things are initialised on import.
Your integration tests will be weaker, because they test less real code and more mocked code. It decreases the actual code coverage. Also, the test suite becomes more fragile, since some tests could depend on the execution order.
It might fix some symptoms, but it won’t fix the problem.
The global state in the previous examples is hardly predictable. Let’s change it and make it manageable. The first step is to take control when the object is initialised. We want to initialise it only when we need it; just in the desired context. This type of refactoring is known as «Extract Method».
Deferred initialisation. Flask example
Flask has a beautiful way of solving this problem — init_app pattern.
It allows you to isolate some global state in an object and control when to initialise it. Also, it used to register some teardown logic for this global object.
# extension.py
class Extension:


    def __init__(self, app=None):
        self.app = app
        if app is not None:
            self.init_app(app)


    def init_app(self, app):
        app.config.setdefault('CONFIG', 'value')
        app.teardown_appcontext(self.teardown)


    def teardown(self, exception):
        ...


ext = Extension()


# app.py
...
ext.init_app(app)In our project, the most problematic global state was the DB. We’re using pytest and the database initialises during importing things in top-level conftest.py. Then the testing database was initialised as a fixture, and all the modules used in the project were monkey patched with this new object. Let’s see how our code could be changed with theFlask-SQLAlchemy extension, that provides aninit_app pattern:
Before:
# database.py


engine, db = create_db(settings.db_url)


# app.py


application = App(__name__)


# conftest.py
import database


@pytest.fixture(scope='session', autouse=True)
def db_schema(db_url):
    engine = create_engine(db_url)


    # Create extensions, tables, etc


    Session = orm.scoped_session(orm.sessionmaker())
    Session.configure(bind=engine)
    session = Session()


    yield session


    Session.remove()
    # Drop tables, extensions, etc


@pytest.fixture
def db(db_schema, monkeypatch):
    db_schema.begin_nested()
    monkeypatch.setattr(database, 'db', db_schema)


    yield db_schema


    db_schema.rollback()
db_schema.close()After:
# database.py
db = SQLAlchemy()


# app.py


application = App(__name__)


from .database import db


db.init_app(application)


# conftest.py
from .app import application
import database


@pytest.fixture(scope="session")
def db():
    # Create extensions, tables, etc
    yield database.db
    # Drop tables, extensions, etc


@pytest.fixture(autouse=True)
def session(db):
    db.session.begin_nested()
    yield db.session
db.session.rollback()Now the database is initialised only when the application initialises — we put the DB into application context. As a consequence, we don’t have to initialise another database connection in tests and make monkey patches. We’re managing this global state — we create a session on demand, only when it is needed.
Application factory
However, application is still global, and it initializes on import. If we didn’t initialise the DB before running the tests, it wouldn’t work. To address this problem the application factory pattern exists. The basic idea is to isolate the application instance creation in a separate function.
# app.py
def create_app(settings_object, **kwargs):
    flask_app = Flask(__name__)
    flask_app.config.from_object(settings_object)
    flask_app.config.update(**kwargs)


    from .database import db


    db.init_app(flask_app)
    db.app = flask_app


    return flask_app


# conftest.py
from app import create_app


@pytest.fixture(scope="session")
def app():
    return create_app("app.settings.TestSettings")


@pytest.fixture
def client(app):
    with app.test_client() as client:
        yield client


@pytest.fixture(scope="session")
def db(app):
    # Create extensions, tables, etc
    yield database.db
# Drop tables, extensions, etcThere are a few benefits of doing this:
- Isolate the side-effects of creating an application on the module-level. An application instance is created after the test session starts
- Flexibility — multiple apps and/ore different settings. It’s available as a fixture, which provides more flexibility (e.g., parametrization)
Running speed vs. test isolation
We fixed the global state on the Python level, but the database itself is a shared resource. It should be in the same state before each test run.
There are a couple of ways of doing this:
- Creating a DB for each test case (slow/isolated)
- Recreate all DB-level entities for each test case (faster / less isolated)
- Wrap each test case in a transaction and roll it back at the end of a test case (fastest, even less isolated)
Each approach has its pros and cons, but the main trade-off is speed vs. test isolation. To be entirely sure that each test case is isolated, you can create a new database for each case, but it will be very slow. You can recreate all the tables for each test case, it will be faster, but you’ll have to take care of re-creating all DB-level features you need for the tests — views/triggers/etc.. Usually, it’s pretty easy to do with migrations. Or, you could create a transaction for each test case and roll it all back at the end — super fast, but what if you need to test some logic, that involves transaction manipulations? For example, Django has TransactionTestCase and TestCase for dealing with different situations. TransactionTestCase truncates all tables and TestCase rolls back a transaction.
Dependency injection
There is another technique that was used in the previous examples but wasn’t mentioned explicitly. Dependency injection.
Dependency injection is a software design pattern which allows you to isolate some logic in a separate entity and pass it into another one as a dependency. Like so:
class BadAirplane:
    max_speed = 900
    distance = 14800


    def fly(self):
        print(
            'Fly {distance} in {time} hours'.format(
                distance=self.distance,
                time=self.distance / self.max_speed
            )
        )


# vs


class Engine:

    def __init__(self, max_speed, distance):
        self.max_speed = max_speed
        self.distance = distance


    @property
    def flying_time(self):
        return self.distance / self.max_speed


class GoodAirplane:


    def __init__(self, engine):
        self.engine = engine

    def fly(self):
        print(
            'Fly {distance} in {time} hours'.format(
                distance=self.engine.distance,
                time=self.engine.flying_time
            )
        )


if __name__ == '__main__':
    engine = Engine(900, 14800)
plane = GoodAirplane(engine)Now, you can pass any engine you want to the airplane and test its logic with different engines, or mock your engine to see if it’s too heavy for an ordinary test. Applying this approach allows you to decouple the execution of a task from its implementation.
For example, you could isolate some hard-to-test logic (e.g., a 3rd party service or some heavy computations) in this “dependency” and pass a mock object in tests instead of the real one.
Flask allows you to write isolated extensions with ease, in pytest you can reuse and parametrize fixtures in tests.
Data & logic separation
When you’re writing tests, usually you use some values as an input for your testing logic, and you expect some other values to be an output of this logic:
def test_something():
assert something('a', 'b') == 'c'But when you hardcode them inside the testing code, it makes it less extendable. If you keep test data separate from the test logic, it will make modifications much more manageable. Dependency injection’s back in the game!
@pytest.mark.parametrize(
    'first, second, expected',
    (
        ('a', 'b', 'c'),
        ('b', 'a', 'd')
    )
)
def test_something(first, second, expected):
assert something(first, second) == expectedIt is especially helpful if you have an extensive test suite — it can help you see similarities in your tests and refactor them or build some reusable tools, that might help you in the future.
More factories
But what if the object you’re testing is more complicated than a string? SQLAlchemy model for example. You could create them manually in a separate fixture, or you could use something like factory-boy.
class User(Base):
    id = Column(Integer(), primary_key=True)
    name = Column(Unicode(20))


class UserFactory(factory.alchemy.SQLAlchemyModelFactory):
    class Meta:
        model = User
        sqlalchemy_session = session   # the SQLAlchemy session object


    id = factory.Sequence(lambda n: n)
name = 'John Doe'Usage is straightforward:
>>> UserFactory()
<User: User 1>
>>> session.query(User).all()
[<User: User 1>]Factory boy is very well integrated with py.test the with absolutely gorgeous pytest-factoryboy. Just register your factories and make sure that they’re imported in your test suite (in the root conftest.py, for example):
from pytest_factoryboy import register


@register
class UserFactory(factory.alchemy.SQLAlchemyModelFactory):
...and now you magically have user and user_factory fixtures.
def test_model_fixture(user):
    assert user.name == 'John Doe'


def test_factory_fixture(user_factory):
assert user_factory().name == 'John Doe'The user fixture corresponds to a simple factory call without arguments. pytest-factoryboy provides a lot of different features that are worth checking out.
Why you should try TDD
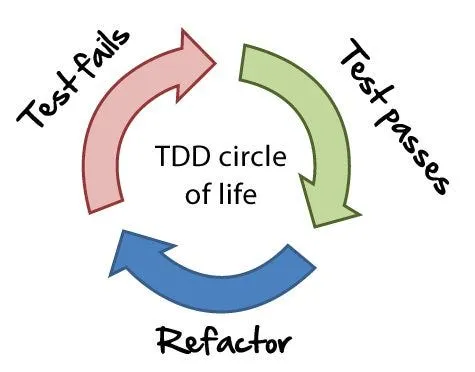
Just a brief recap, what TDD is:
- Write a failing test
- Add/modify the code so that the test passes
- Refactor the test & code
Why?
It just saves time and consequently money
For example, you’re building a new API with Flask, and you want to add a user’s listing in the beginning:
def test_users_listing(client, user):
    response = client.get('/users')
    assert response.status_code == 200
assert response.json == [{'id': user.id, 'name': user.name}]Then update your handler with the code that will query users, and the test will pass. After that, you do the next feature in the same way, and then another one, and so on. In the end, you’ll have each feature tested.
Then, for example, you’ll add a new field to the user — age. You’ll write a test for it, and it will pass. But if your listing will not restrict the output fields the listing test will fail after adding the age field — you broke the interface, but luckily you’ll know about it as soon as you run your tests. Fix it any way you want and go to the next feature.
Rapid and iterative development process is a beautiful feature of TDD. You’ll see problems very fast just by running a test suite. With pytest you don’t even have to re-run it — you could use looponfailing mode from the pytest-xdist plugin:
pytest -f testsAlso, you’ll trust your test suite, and if something fails in production, you’ll add a regression test. It makes your more confident about your code when you’re doing refactoring or adding a new feature. You’ll know that the new feature won’t break other features and it’s safe to add.
It could help you with building something big — split that big thing into small, functional pieces, write tests and make them pass.
But it’s not a silver bullet. It doesn’t mean that you won’t have to write other types of tests or won’t have to use different approaches. Sometimes it’s just more straightforward to do something in a way you’re with. However, consider adding TDD to your arsenal, it’s worth trying to improve your development experience.
Testing shows the presence, not the absence of bugs.
- Edsger W. Dijkstra
Cheers!
Would you like to write testable code with Dmitry? Check our open positions.
References:
- http://wiki.c2.com/?GlobalVariablesAreBad
- https://www.toptal.com/qa/how-to-write-testable-code-and-why-it-matters
- http://flask.pocoo.org/docs/1.0/extensiondev/
- http://flask.pocoo.org/docs/1.0/patterns/appfactories/
- http://python-dependency-injector.ets-labs.org/introduction/di_in_python.html
- https://dmerej.info/blog/post/why-you-should-try-tdd/
- http://blog.cleancoder.com/uncle-bob/2016/03/19/GivingUpOnTDD.html